 CotrievalAI
Machine / 01Created per booking
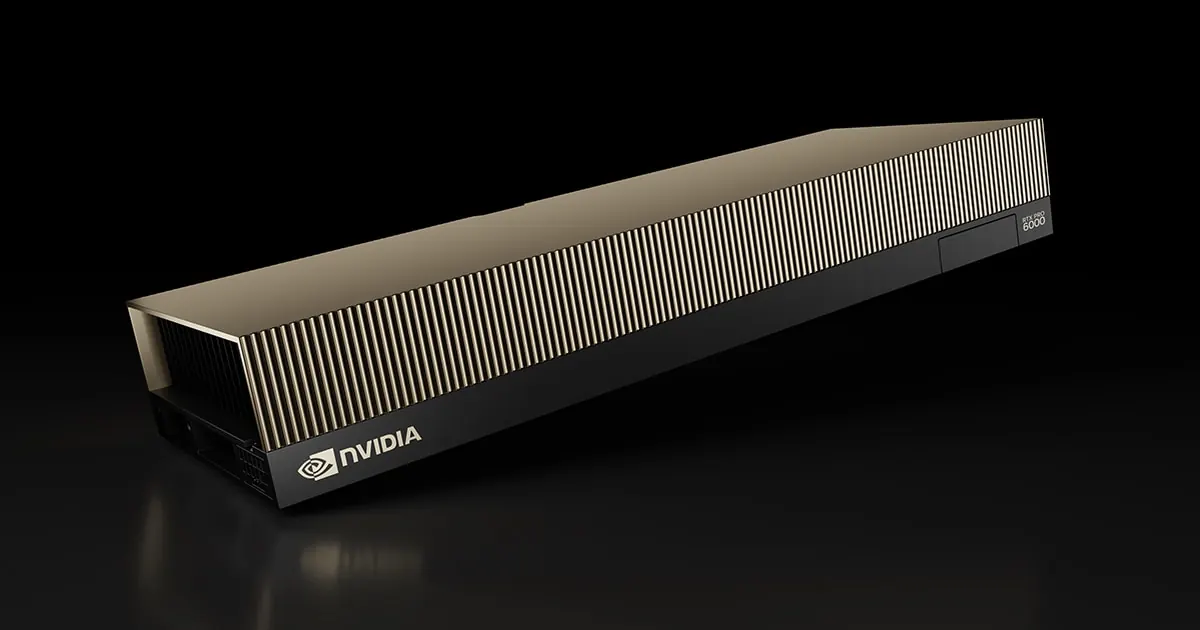
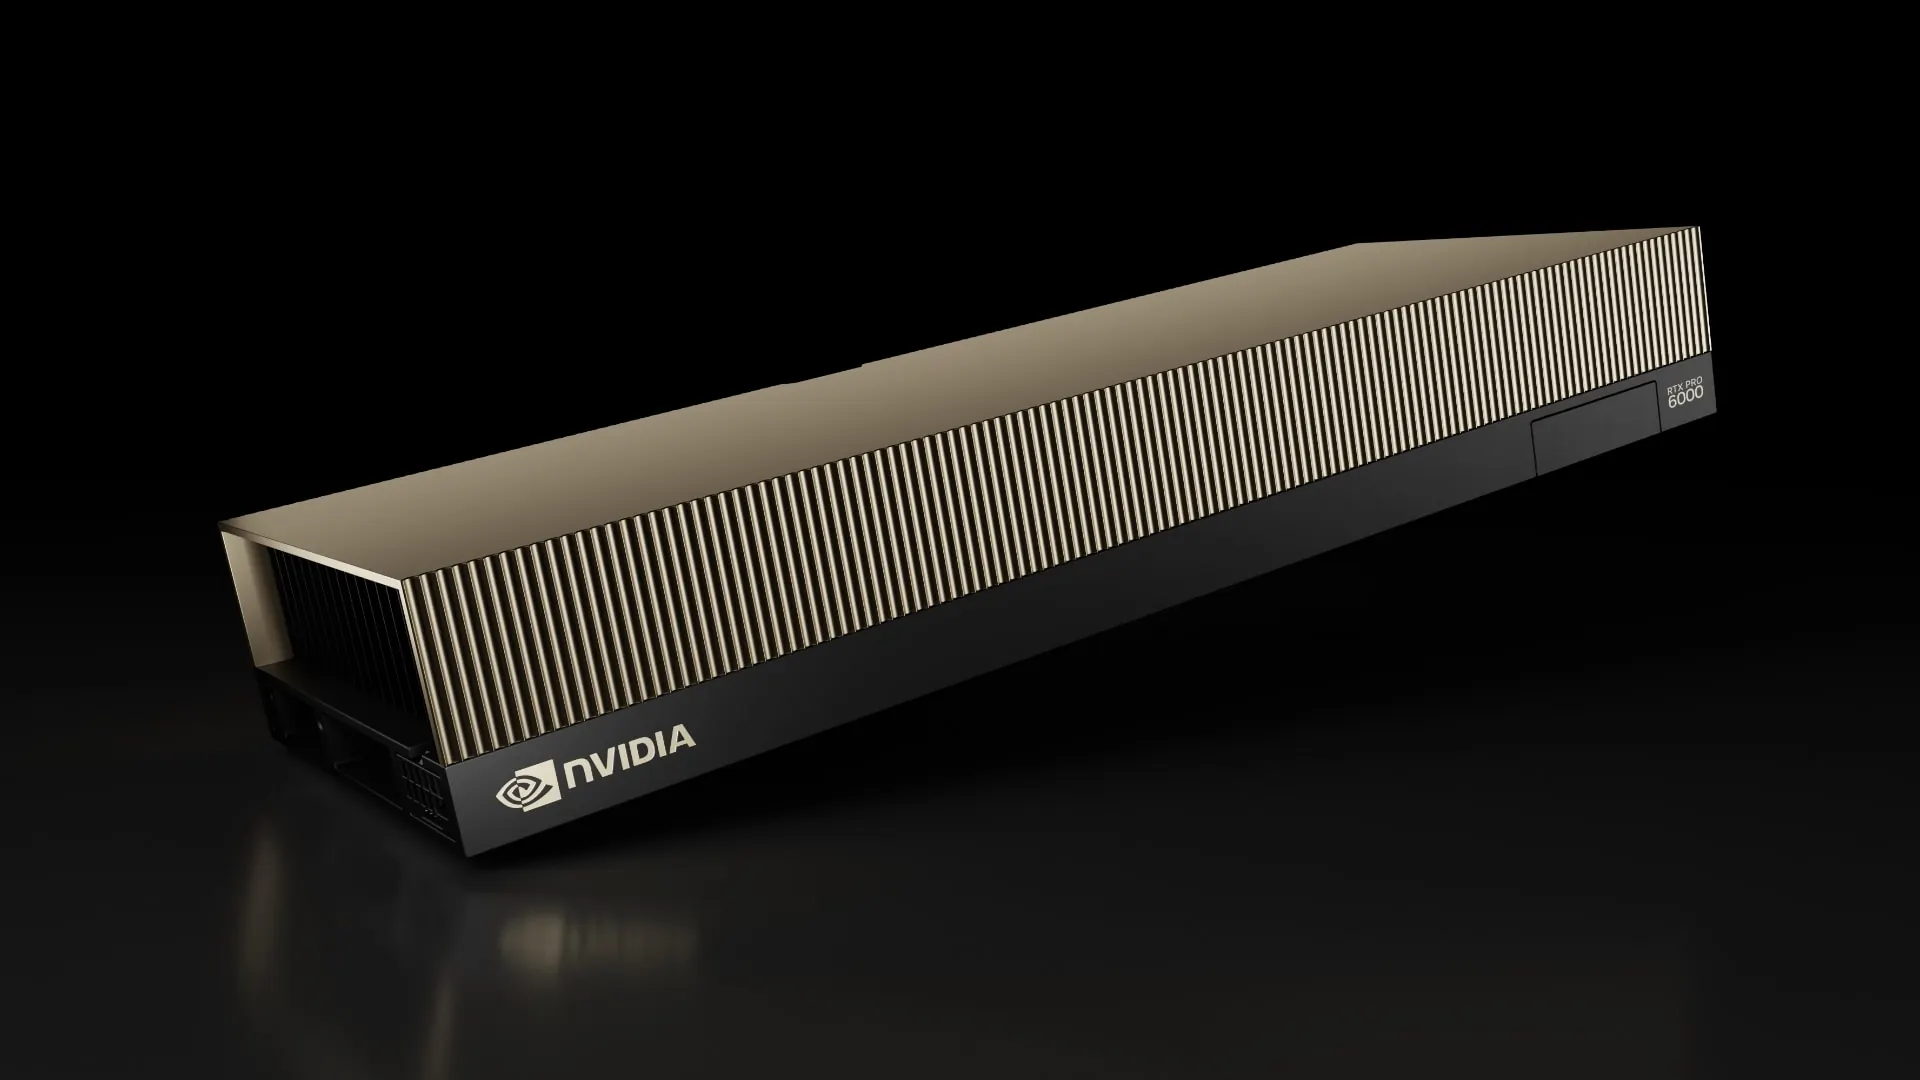
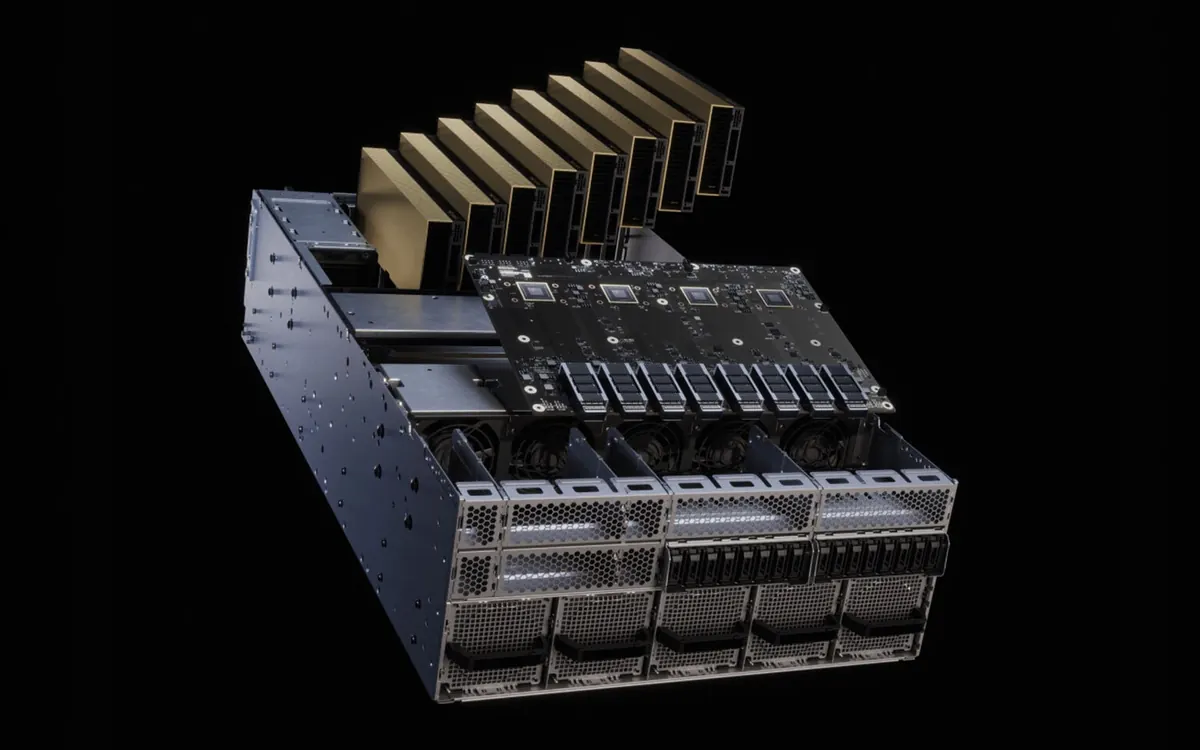
4× RTX PRO 6000
or 4× H100 80GB · GLM-5.3-Flash, uncensored
Price per hour quoted at booking
- Model
- An uncensored build of GLM-5.3-Flash for long coding, research and security work
- Context
- 1M tokens
- Speed
- 226–231 tokens a second for one user on 4× H100, about 145 on 4× RTX PRO 6000 (measured Oct 14)
- Serving
- vLLM, with an OpenAI-compatible API
- Ready
- 10 to 15 minutes after booking
- Lifetime
- Deleted when you end it, or after 6 hours
- Region
- Wherever GPUs are free: the US, Europe or Australia